← All PDF guides
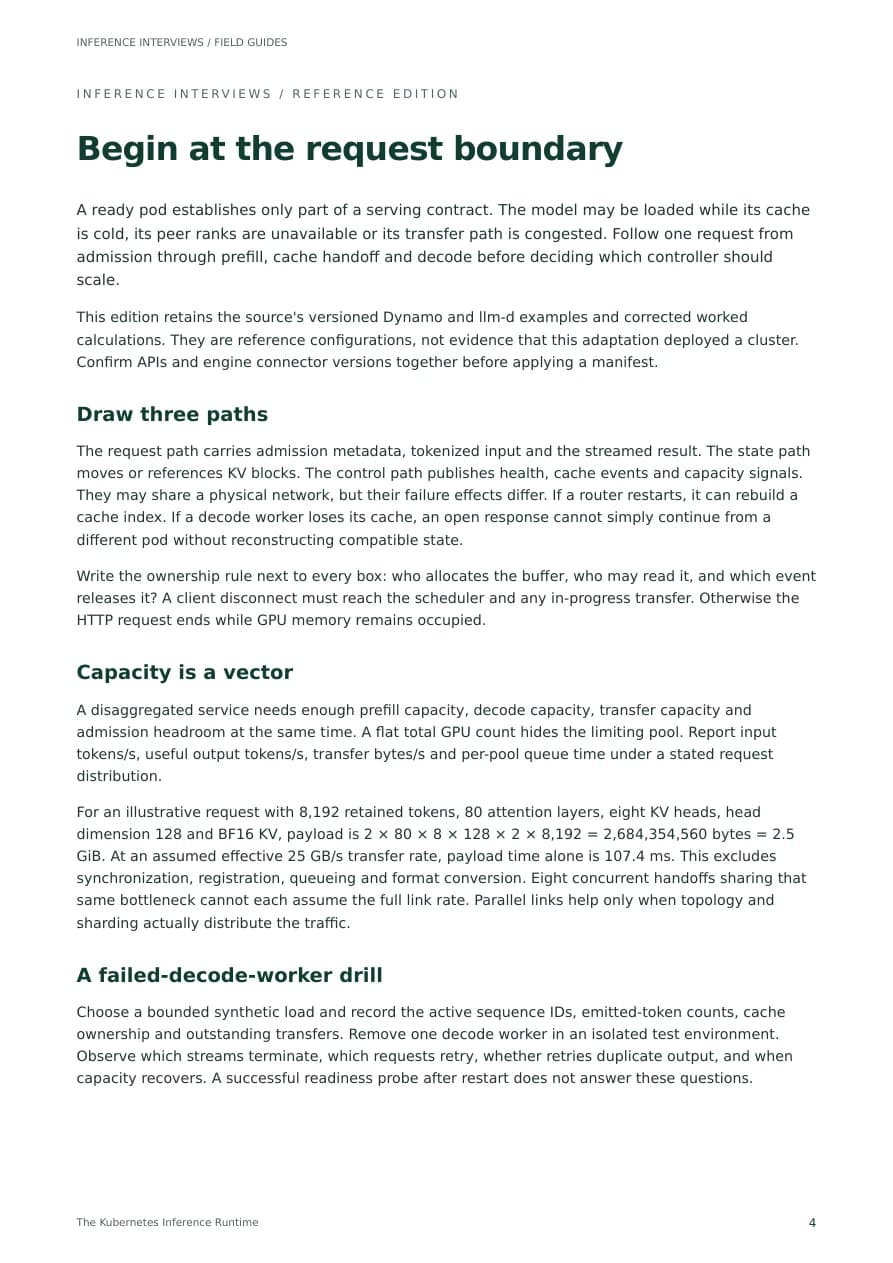
Preview: the opening inference workbook page.
FIELD GUIDE 03 / OCTOBER 2026
The Kubernetes Inference Runtime
Route the request. Transfer the state. Keep decoding.
Follow cache-aware routing, prefill and decode pools, multi-node workers and rollouts through a Kubernetes serving graph, with worked capacity and failure cases.
106 pages25 reference chaptersSearchable PDF
Sign in to check download access
The complete PDF requires active paid Premium or an eligible full-access grant. Referral access does not include downloads.
THE DECISIONS INSIDE
Defend where request state lives, how a failed worker is replaced and what evidence justifies splitting prefill from decode.
- 01Map request, cache and control traffic
- 02Budget KV transfer and pool ratios
- 03Place multi-node and expert-parallel workers
- 04Compare versioned Dynamo and llm-d paths
- 05Drain, recover and test the serving graph
Mechanisms and deployment examples retain their source edition and pinned versions. Adapted October 25, 2026.
PUT IT TO WORK